

- Security researchers reportedly used Anthropic’s Claude to breach an OpenAI employee’s account and reach internal company systems
- The breach reportedly took under 72 hours to complete
- The researchers have described the exercise as authorized white-hat testing rather than a malicious attack
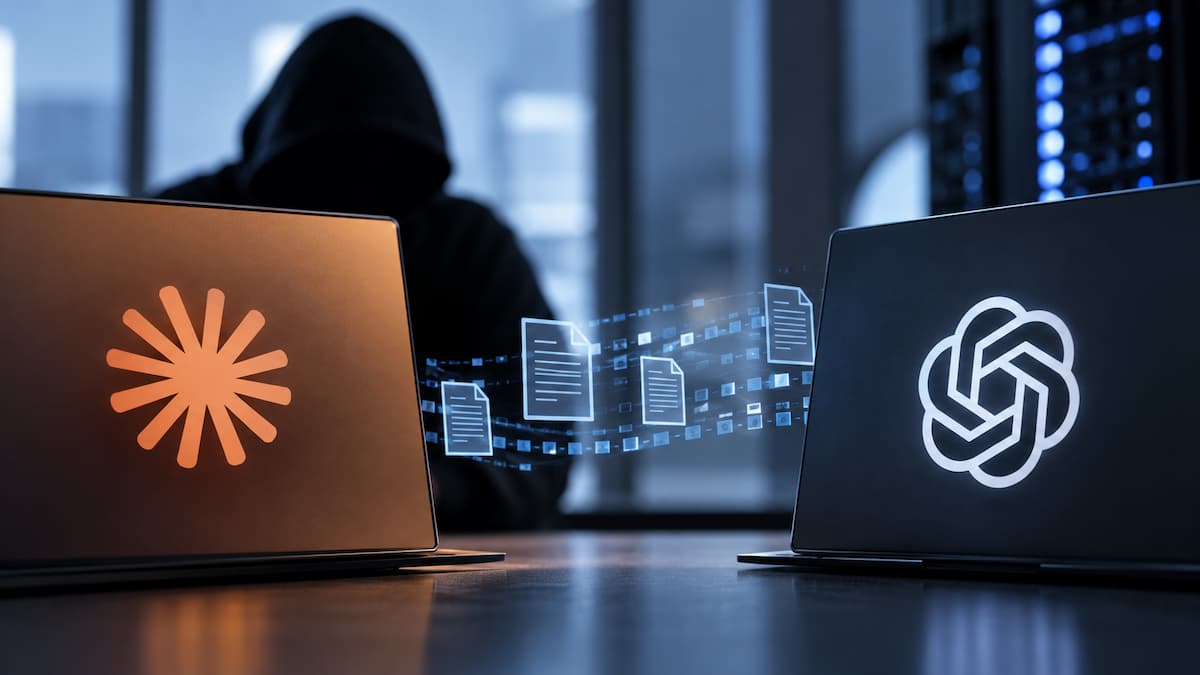
Independent security researchers reportedly used Anthropic’s Claude AI system to breach an OpenAI employee’s account and gain access to internal company systems, completing the exercise in under 72 hours. The researchers have characterized the effort as authorized white-hat security testing intended to demonstrate the current offensive capability of AI agents when directed at real-world corporate infrastructure, rather than an unauthorized attack carried out for malicious purposes.
The demonstration is significant because it involves one major AI lab’s model being used to penetrate the internal systems of a direct competitor, illustrating a capability that security researchers across the industry have warned about in more abstract terms for some time. Using an AI agent to autonomously plan and execute steps of a security breach, including social engineering, credential compromise, or lateral movement within a network, has been discussed as a theoretical risk in AI safety research for years, but concrete demonstrations against a real, named target’s infrastructure are less common and tend to draw significantly more attention.
Neither Anthropic nor OpenAI has issued a detailed public statement fully confirming every specific detail of the breach as researchers have described it, which is a common pattern following disclosed security incidents while internal investigations and remediation are still underway. The involvement of a competitor’s AI model in the exercise, rather than the affected company’s own tools, has added a layer of attention to the story beyond what a comparable breach using conventional hacking techniques would likely have received.
The incident arrives at a moment when both AI safety researchers and crypto security specialists have separately flagged rising concern about AI-assisted attacks, including a reported surge in AI-assisted malware targeting blockchain infrastructure. Taken together, the pattern suggests the gap between AI models being used defensively, to find and patch vulnerabilities, and offensively, to actively exploit them, is narrowing faster than many security teams have planned for, regardless of which specific lab’s technology is involved in any individual case.
White-hat exercises of this kind typically operate under strict, pre-negotiated rules of engagement, including explicit authorization from the target company and defined boundaries on what systems or data the researchers are permitted to access during the test. Details of exactly what authorization framework governed this particular exercise, including whether OpenAI itself commissioned or consented to the test in advance, have not been fully disclosed, which is part of why some security researchers have called for greater transparency around how the exercise was structured before drawing broader conclusions about the state of AI-assisted offensive security capability from a single reported case.
Disclaimer: Cryip's content is strictly for educational and informational purposes and does not constitute financial, legal, or investment advice. Cryptocurrency involves significant risk, and readers assume full responsibility for their own financial decisions. Asset references are never endorsements.
To make complex crypto topics accessible to readers at all experience levels, our team uses AI tools strictly to refine language, correct grammar, and simplify terminology. AI is never used to draft facts, source information, or form conclusions. Every article is fact-checked and approved by a human editor before publication. Read our full AI Use & Content Policy.